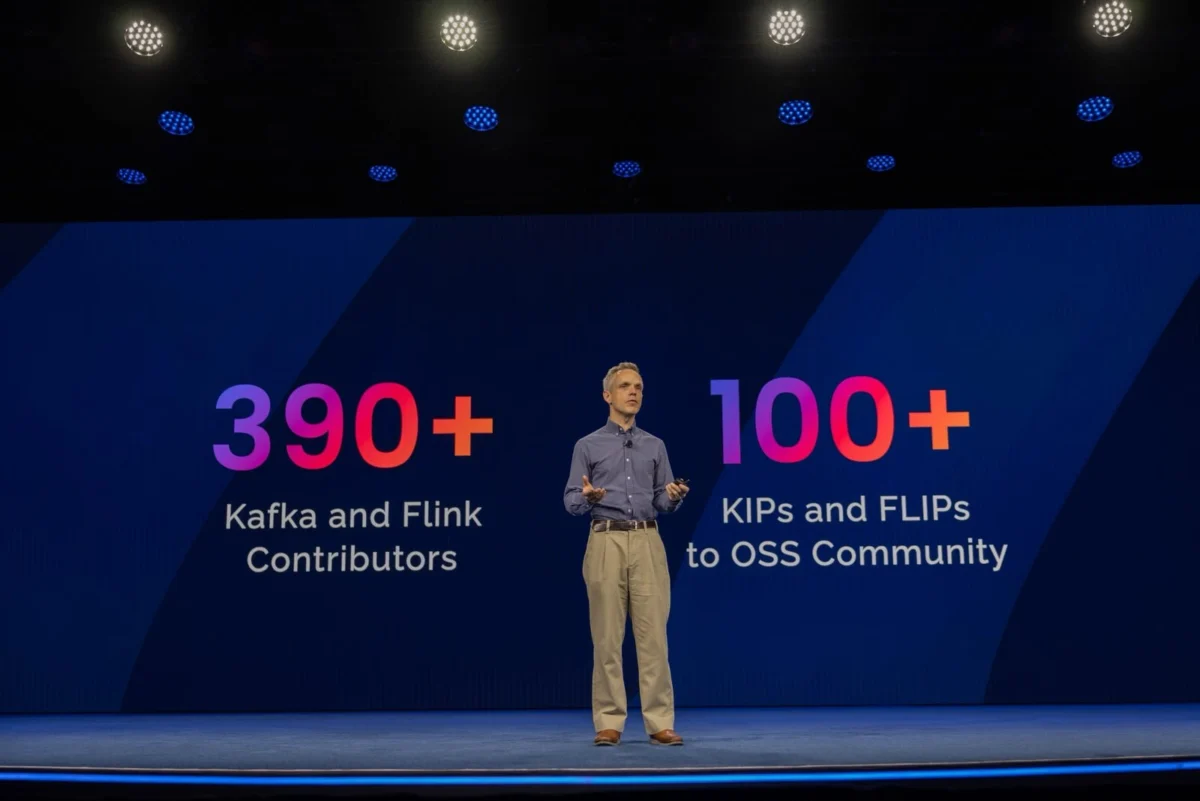
Data velocity has officially become the primary bottleneck for enterprise artificial intelligence. On November 6, 2026, Confluent officially unveiled its groundbreaking Streamhouse architecture, a unified platform designed to capture, process, govern, and serve real-time data streams within a single operational layer. As organizations increasingly deploy autonomous AI agents and automated operational workflows, traditional data architectures—namely data lakes, data warehouses, and static data lakehouses—are increasingly falling short. These legacy storage paradigms excel at batch reporting and periodic historical analysis, but they inherently introduce latency. When an enterprise relies on fragmented databases where inventory updates, customer touchpoints, and logistics statuses fail to sync in real-time, AI agents inevitably make decisions based on stale information. Confluent’s Streamhouse directly addresses this systemic vulnerability by serving as a continuous, low-latency operational layer that provides consistent, up-to-the-second business context across the entire enterprise ecosystem.
The evolution of enterprise data management over the past two decades has moved from transactional databases to complex analytical warehouses and scalable cloud storage lakes. However, the paradigm shift toward generative AI and autonomous agents has exposed a critical architectural flaw: AI models are only as effective as the data context they consume at the exact moment of execution. Historically, enterprises have struggled with siloed systems where operational data is updated asynchronously. For instance, in a complex airline scenario, an operational tracking system might log an aircraft’s physical location, a scheduling engine records estimated departure times, and a separate booking platform manages seat inventory. If these systems update out of sequence, an AI-driven customer service agent or automated booking tool could inadvertently recommend a connecting itinerary that appears valid on paper but is operationally impossible due to a delayed inbound aircraft. Streamhouse solves this multi-system fragmentation by orchestrating changes through continuous event streaming. Every operational mutation—whether it is a shifted flight path, a delayed departure, or a live seat reservation—is processed instantaneously as an event, ensuring that customer-facing applications, internal microservices, and AI models operate from a single, synchronized source of truth without requiring companies to rip and replace their existing data warehouses.
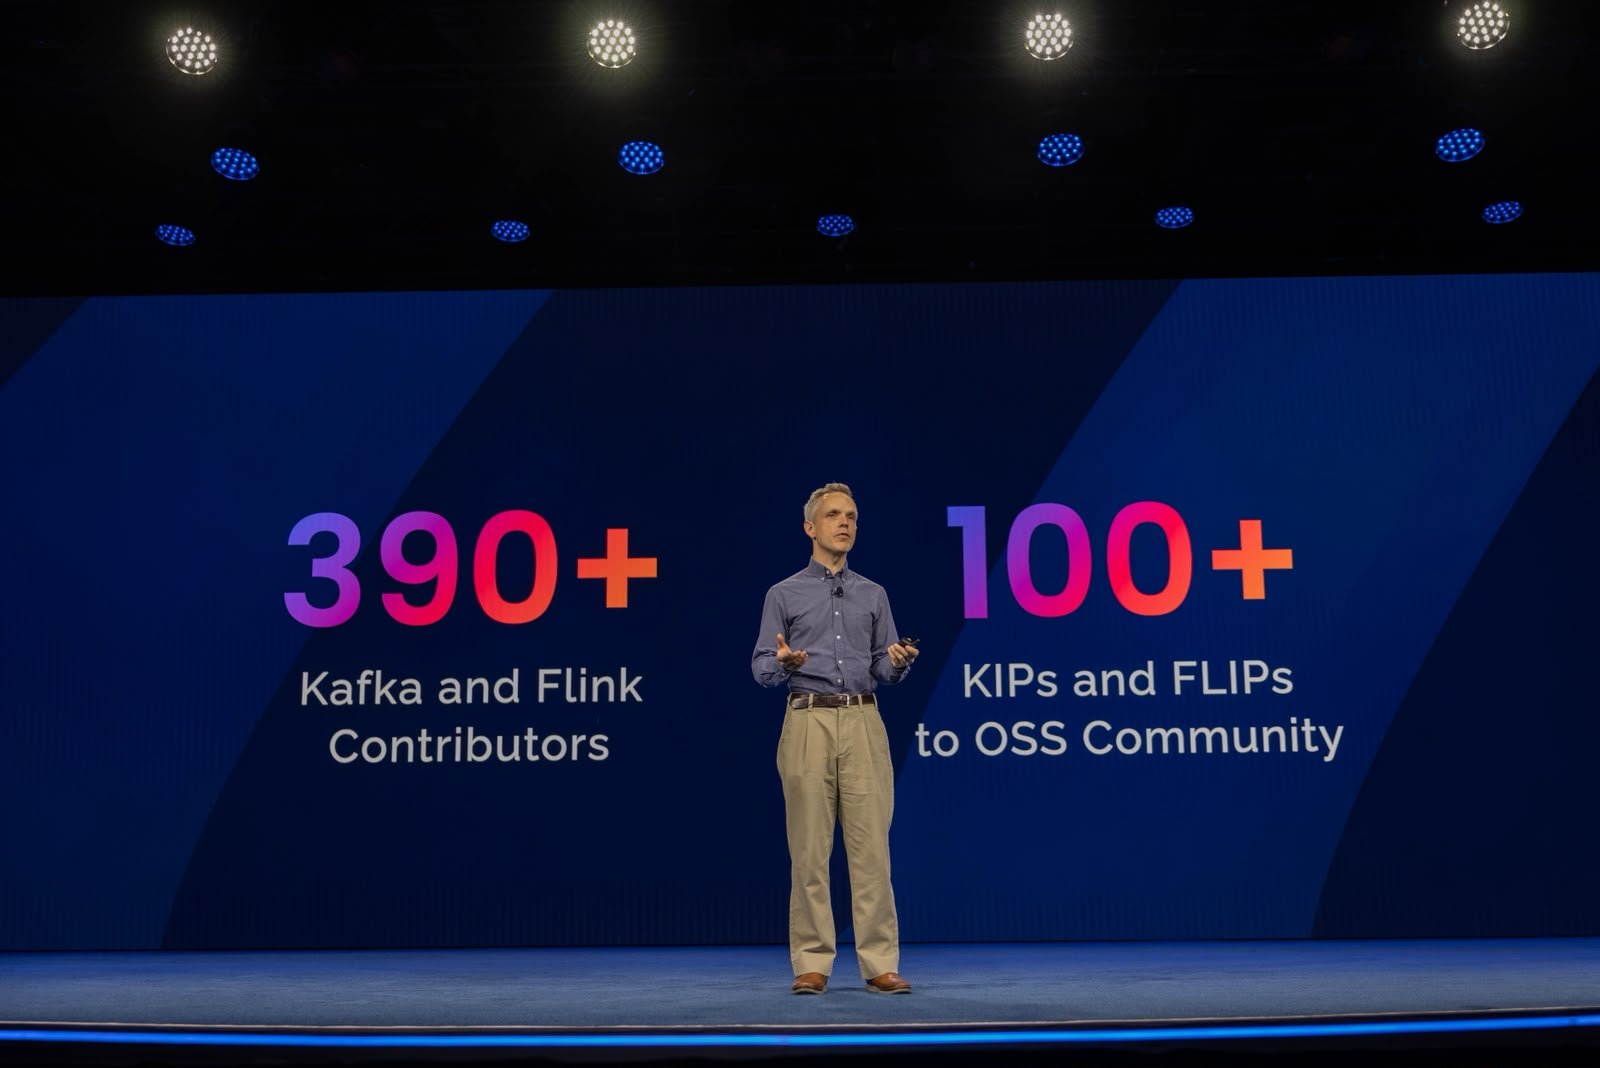
To bring the Streamhouse vision to life, Confluent has systematically evolved its foundational Data Streaming Platform (DSP) around five distinct pillars: Stream, Connect, Process, Govern, and Query. The architectural foundation begins with Stream, powered by Apache Kafka and the high-performance Kora engine, which captures and streams business events across enterprise landscapes with internal test latencies dipping below one millisecond. The Connect pillar bridges disparate legacy environments via a robust library of more than 150 managed and custom connectors, facilitating hybrid connectivity across multi-cloud and on-premises deployments. Next, the Process pillar leverages Apache Flink to continuously transform, enrich, and aggregate data streams as events occur, while also supporting batch workloads for initializing streaming pipelines. To maintain enterprise compliance, the Govern pillar enforces strict guardrails through centralized data catalogs, automated data quality checks, schema evolution management, encryption standards, lineage tracking, and granular access controls. Finally, the newly introduced Query pillar completes the stack, enabling applications, analytical systems, and AI models to directly query the moving data streams through innovative consumption models.
At the heart of the Streamhouse rollout is the general availability of Lightning Tables on Confluent Cloud via Amazon Web Services (AWS), representing a monumental leap forward in real-time data consumption. Lightning Tables act as read-only, stream-native presentation layers that continuously materialize Apache Kafka data topics directly into queryable database tables. Rather than forcing organizations to continuously copy high-velocity data into separate operational databases or caching layers—a process that introduces synchronization lag and infrastructure bloat—Lightning Tables allow applications to read the latest operational state directly. Internal testing by Confluent indicates that the end-to-end latency from event generation to query availability sits at approximately 100 milliseconds, with individual query latencies ranging from 10 to 100 milliseconds at scale, supporting throughputs exceeding 1,000 queries per second. Alongside Lightning Tables, the Query pillar incorporates Confluent Tableflow, which seamlessly publishes streaming data into open table formats for downstream data warehouses, and the Real-Time Context Engine, which supplies live operational context to AI agents via the Model Context Protocol (MCP).
Global enterprises across industries have already begun embracing the Streamhouse architecture to eliminate batch-processing bottlenecks and modernize their digital infrastructure. Greg Taylor, Senior Vice President and General Manager for Asia Pacific at Confluent, noted that organizations throughout the APAC region are rapidly expanding their digital service footprints while grappling with heightened customer expectations for instantaneous responses. According to Taylor, autonomous AI agents require an accurate, unblemished view of organizational reality to execute complex workflows safely, a mandate that makes the continuous, managed data foundation of Streamhouse an operational necessity. Global professional services giant Accenture has publicly validated this architectural shift. Thomas Mahaffey, Head of Data Strategy for SAI at Accenture, detailed how the firm previously struggled with traditional batch-based architectures and point-to-point data integrations that created heavy operational overhead and delayed business insights. By adopting Confluent’s streaming architecture to decouple data producers from consumers, Accenture successfully transformed high-volume event streams into reusable, managed real-time data products, compressing time-to-insight from months down to mere days.
Similarly, Extend, an innovative AI-driven commerce platform, has integrated the Streamhouse architecture into its core infrastructure to support mission-critical workflows such as merchant onboarding, dynamic pricing algorithms, and real-time fraud detection. Jonathan Kropp, Director of AI and Architecture at Extend, emphasized that legacy message queues and static data lakes severely limited the company’s ability to replay historical events, enforce strict schemas, and maintain system resilience under heavy loads. By deploying a serverless Streamhouse architecture powered by Confluent Cloud, Extend established Apache Kafka as an immutable, real-time operational backbone capable of feeding multiple microservices asynchronously. This technological leap not only optimizes operational agility but also aligns with broader enterprise strategies, such as Confluent’s deepening ecosystem integration with IBM. By combining real-time streaming capabilities with IBM’s enterprise-grade integration, governance, and AI tooling, Confluent is positioning Streamhouse as the definitive middleware for hybrid cloud environments. Ultimately, by shifting the role of data streaming from simple point-to-point delivery to a comprehensive operational context engine, Streamhouse ensures that future enterprise applications and AI agents act on the pulse of the present rather than the history of the past.

